Summary
Expectations can influence cues, treatment and scoring. Clever Hans shows why a correct response does not by itself identify the ability being tested.
At a glance
The experimenter effect occurs when expectations or behavior of investigators influence measured results. Blinding, standardized procedures and careful scoring help distinguish the tested factor from cueing or interpretation.
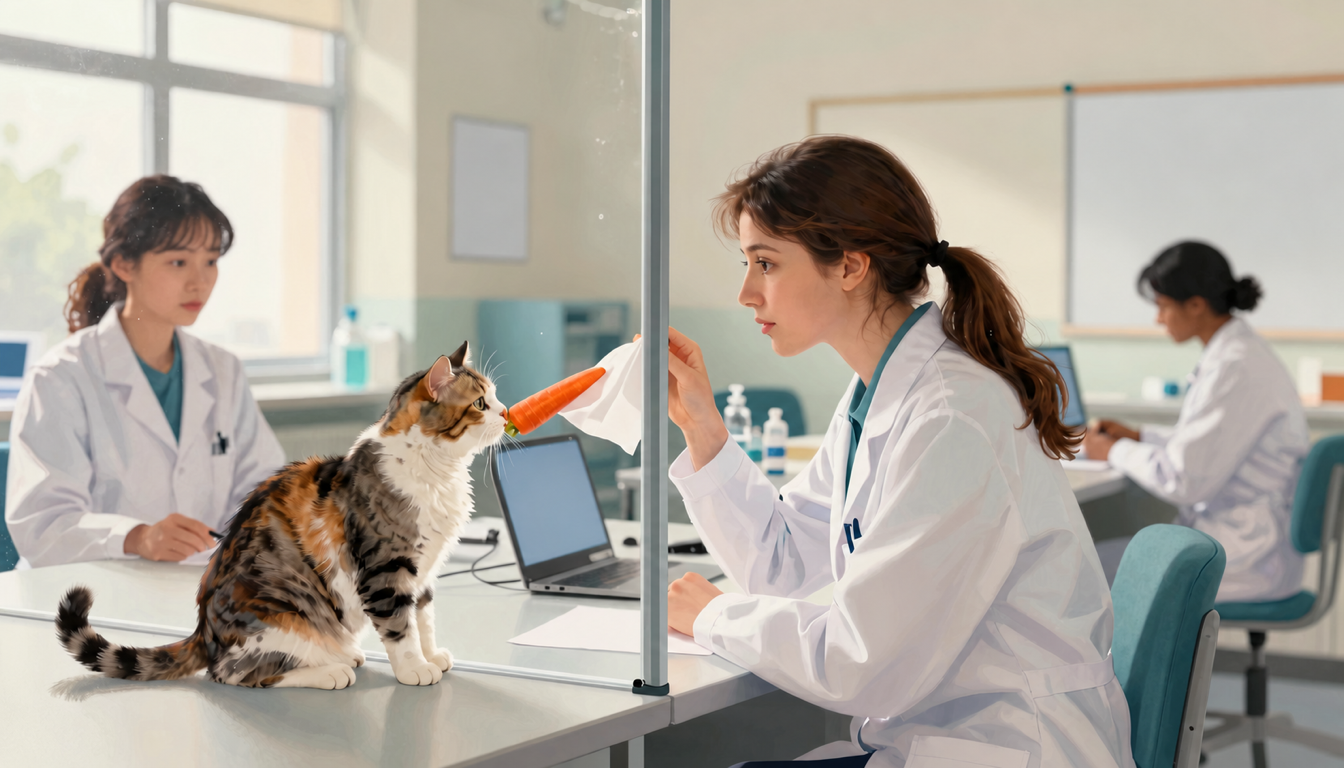
A cat is shown a carrot and a tissue. Its owner names one, and after some hesitation the cat puts a paw on it. The performance is charming—and it raises a harder question than whether the animal chose correctly. What information did it use to choose?
The spoken word is one possibility. The owner’s gaze, posture, tone or response to a movement may be others. A short video cannot separate them. To learn what the animal understands, we need a test that distinguishes the explanation we hope for from the alternatives.
That is the central lesson of the experimenter effect: the person conducting a test can become part of what the test measures.
Clever Hans answered a different question
Clever Hans was a horse whose apparent ability to answer questions attracted extraordinary attention. His owner, Wilhelm von Osten, believed that training could develop abilities resembling human knowledge. Hoof tapping appeared to provide answers to numerical questions and other tasks translated into numbers.
Oskar Pfungst investigated the performance. In his original account, controlled observations showed that subtle movements from the questioner could guide when the horse began or stopped responding. The human did not have to intend to help or even notice the movement.
The result was not an encyclopedia in equine form. It was an interaction in which information about the answer reached the animal through a route observers had initially overlooked. That is a remarkable ability of a different kind, and an important distinction about what had actually been demonstrated.
Return to the cat. Cueing is a plausible alternative explanation, not a conclusion established merely by remembering Hans. An animal might learn words, locations, gestures or a combination. Good tests keep those possibilities apart instead of choosing whichever account is most entertaining.
How expectations can enter a test
A researcher may have particular expectations about which group will perform better. Those expectations can affect more than the final interpretation. Instructions may sound more encouraging, an ambiguous response may receive another chance, or handling may differ slightly between groups.
Scoring provides another route. If a response is open to judgment, knowing the expected result can influence what counts as correct. An honest person can introduce bias without deciding to falsify anything. That is why safeguards should not rely solely on confidence in the researcher’s good intentions.
A result may also reflect an actual change in behavior. Encouragement or pressure can influence a participant, so the measured difference is not necessarily a recording error. The question is whether the difference comes from the factor the experiment was designed to test.
This matters especially when a striking first report becomes the starting point for later work. A small or ambiguous observation can acquire a strong interpretation through repetition in discussion, even before the underlying alternative explanations are resolved.
Animals and handlers form a testing system
Animal experiments make the cueing problem particularly visible because the animal and human often respond continuously to each other. Preventing the animal from seeing the operator can block one route of information, but sound, timing and other differences may still need control.
A testing apparatus or partition is therefore a tool for a particular problem, not a guarantee that every cue has disappeared. The researcher must ask which information is available under each condition and whether it differs systematically with the desired answer.
The original article also points to detection dogs, where the handler’s interpretation and behavior are part of the outcome. Lit and colleagues’ study specifically investigated how handler beliefs affected scent-detection outcomes. It offers a reason to control what handlers know during evaluation, rather than assuming the dog’s response can be interpreted independently of the human partner.
The practical lesson is narrower than “dogs cannot detect scents.” A performance test must establish what produced the alert and how it was identified. Reliable capability and vulnerability to cueing are not mutually exclusive.
Labels can change the treatment people receive
The classic rat-training example asks what happens if handlers believe otherwise comparable rats are especially bright or dull. If handling, patience or recording changes with the label, a later difference may appear to confirm the initial description. The design illustrates why assigning a label is itself something to study, not a neutral background detail.
A classroom version asks a related question: might telling teachers that certain pupils are likely to develop rapidly change the opportunities, encouragement or feedback those pupils receive? The possibility concerns a chain of interaction. A belief would have to affect treatment, and that treatment would have to matter for the measured outcome.
It does not follow that expectations determine intelligence or that an optimistic teacher can produce any chosen result. Existing knowledge of a pupil, age, classroom conditions and the way an outcome is measured can all matter. A label is one influence within a complicated setting.
The term Pygmalion effect is often used for expectation-related changes in performance, recalling the sculptor whose statue came to life. It is related to the broader expectancy problem, but it should not replace the distinctions between cueing, biased measurement and changed treatment.
Reduce the routes by which an answer can leak
Blinding keeps relevant people unaware of information that could shape their behavior or judgment. An experimenter who does not know group assignments has less opportunity to treat groups according to those labels. Independent blinded scoring can address a different route: interpretation of the response.
A double-blind design usually involves blinding both participants and relevant investigators. The exact people and information concealed should be stated, rather than assuming that the label alone describes every safeguard. Some experiments cannot blind everyone, making other controls especially important.
Standardization also helps. Consistent instructions, planned scoring rules and comparable procedures reduce opportunities for expectation to change the task. Replication can then test whether a finding holds beyond one set of people and circumstances.
Keep everyday judgments open to revision
Outside a laboratory, labels can shape what we notice. If we decide that someone is unkind, later ambiguous behavior may look like confirmation. If we decide that we cannot finish it before beginning a task, an ordinary obstacle can feel like proof of inability.
This is related to the article’s lesson, although selective interpretation is not identical to giving a participant an inadvertent cue. Sometimes our judgment changes our behavior toward someone; sometimes it mainly changes the evidence we attend to. Distinguishing those routes helps us respond more thoughtfully.
Treat other people’s judgments and opinions as information to consider rather than a final definition of who you are. Extend the same openness to your own judgments of others. Expectations can influence an interaction, but they need not be mistaken for destiny—or for a complete explanation of the result.
Frequently asked questions
Did Clever Hans demonstrate arithmetic understanding?
Pfungst’s investigation showed that subtle human movements could guide the horse’s responses.
Does a cat video prove cueing?
No. Cueing is an alternative to test, not a conclusion from the video alone.
Is experimenter blinding the same as double blinding?
Not necessarily. Double blinding usually includes both participants and relevant investigators; the actual arrangement should be specified.
Do expectations determine someone’s future?
No. They may influence treatment or judgment, but they are not destiny.